TASK-SPECIFIC MODEL TRAINING

CoreWeave
Model Distillation

Train a smaller model for the task you already run in production. Turn real examples into training data, compare candidates against your current model, and move traffic when the results meet your quality bar.

From production traffic to a specialized model

Once you've iterated on your prompt until a frontier model delivers the quality you want in production, you can test whether a smaller model is a better fit. CoreWeave Model Distillation connects production examples, managed training, and evaluation against the model you run today, so you can make that decision before moving traffic.

Fit the model to the task

Train a smaller open-weight model on examples from your task using Serverless supervised fine-tuning (SFT). CoreWeave manages the training infrastructure, so you can focus on the behavior you want the model to learn.

Prove it on your own traffic

Compare candidates against the model you run today on held-out examples from your own traffic. Inspect individual judgments and behavioral differences, not just aggregate scores, before deciding whether to switch.

Close the production loop

Use new production traffic to build the next dataset and improve the next candidate. Keep data curation, training, evaluation, and rollout connected as your task changes.
Deploy

Your model, your move

Roll out traffic in slices, roll back with one change, and build on open-weight models that stay portable.

Move traffic gradually

Deploy through CoreWeave Inference and set the share of requests each model receives. Start with a small slice, monitor the results, and adjust traffic weights as your confidence grows.

Keep your current model as a reference

Keep the model you are replacing available as a reference stream. Continue comparing behavior on live traffic and shift traffic back if the candidate does not meet your quality bar.

Keep your model portable

Every candidate starts from an open-weight base model, so the model you ship isn't tied to one vendor's model family.

No separate fee

Model Distillation isn't billed separately. You pay standard rates for the services the workflow uses, including Serverless SFT at $2.70 per GPU-hour, prorated by active training time, plus Serverless Inference, Agent Lens, Weights & Biases Models, and artifact storage.

Model Distillation is part of CoreWeave Forge

Turn production evidence into model improvement

CoreWeave Forge connects the data, training, evaluation, and inference behind your AI application. Model Distillation brings those capabilities together to improve task-specific models.

Improve

Curate examples from production, train specialized candidates, and compare them against the model you run today. Roll out the candidate that meets your quality bar, and then use new traffic to inform the next iteration.

FAQS

Frequently asked questions

What is Model Distillation?

When should I use Model Distillation?

Can I use my production data for Model Distillation?

How can I keep weak responses out of training data?

How do I know whether the distilled model is better for my task?

Can I compare multiple model candidates?

How do I move a distilled model into production?

Is my distilled model portable?

Related resources

Blog

CoreWeave Forge: Turn AI Iteration Into Compounding Improvement

Video

CoreWeave Forge: We're Built For This

Press Release

CoreWeave Forge Launches, Turning the AI Loop Production Run Into a Better Model and Agent

Builder Resource Center: Learn from every run

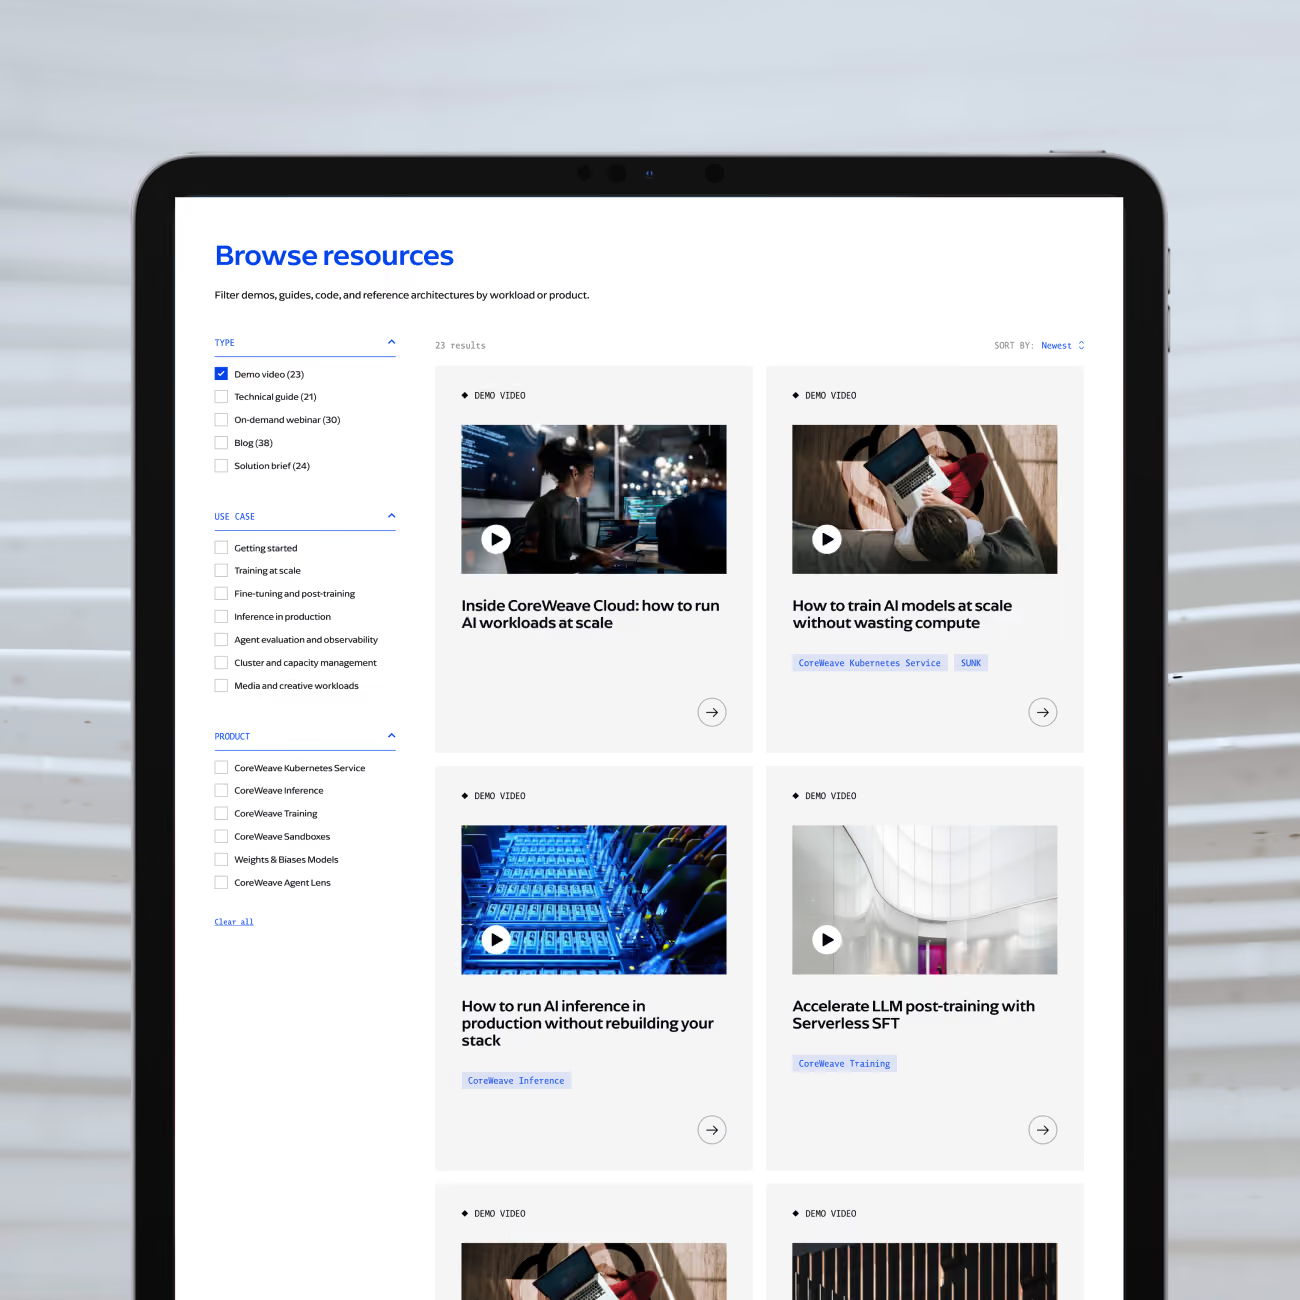
Explore demos, code, and technical resources for every stage of the AI loop. Learn how researchers, developers, and CoreWeave engineers build, observe, evaluate, and improve AI systems—and put those insights to work.

EARLY PREVIEW

CoreWeave Model Distillation

Most production tasks run on a model far bigger than the job needs, and you pay for that on every call. CoreWeave Model Distillation trains a smaller model for your task and tests it head-to-head against the model you run today, on your own production traces.

This is an early, hands-on preview of our model distillation workflow, in which we work directly with you and a small group of our engineering teams to refine the end-to-end process as it takes shape.

Make moving your traffic a decision you can defend, not a leap. Leave your details, and our product team will reach out to see if it’s a fit.

Get started

Bring one task. Test a specialized model.

Start with an expensive, repeatable task your current model already handles. Request private preview access to turn real examples into a smaller model and compare the results before moving traffic.