EXPERIMENT TRACKING

Weights & Biases Models

With over a billion runs tracked, Weights & Biases Models gives pioneers the tools they need to run more experiments, compare results faster, and build higher-quality models with confidence.

Turning experiments into better models

Build better models faster

Make your teams more productive with tools to iterate on models, analyze results, and collaborate seamlessly. Track, version, compare, and reproduce multimodal experiments, visualize performance, uncover insights, and identify improvements or regressions to get to market faster.

Scale with performance and reliability

Capture experiment data with low latency, high throughput, and dependable logging at any scale. Run hundreds of thousands of experiments and track thousands of metrics and millions of data points without slowing down critical training workloads. Quickly upload or download large model files at frontier AI scale.

Build on anything, locked-in to nothing

Use the tools, frameworks, and infrastructure that work best for your team. Built-in integrations simplify workflows, while flexible deployment options provide control across managed cloud, private cloud, on premises, and hybrid environments.
Experiment Tracking

Accelerate experiment velocity

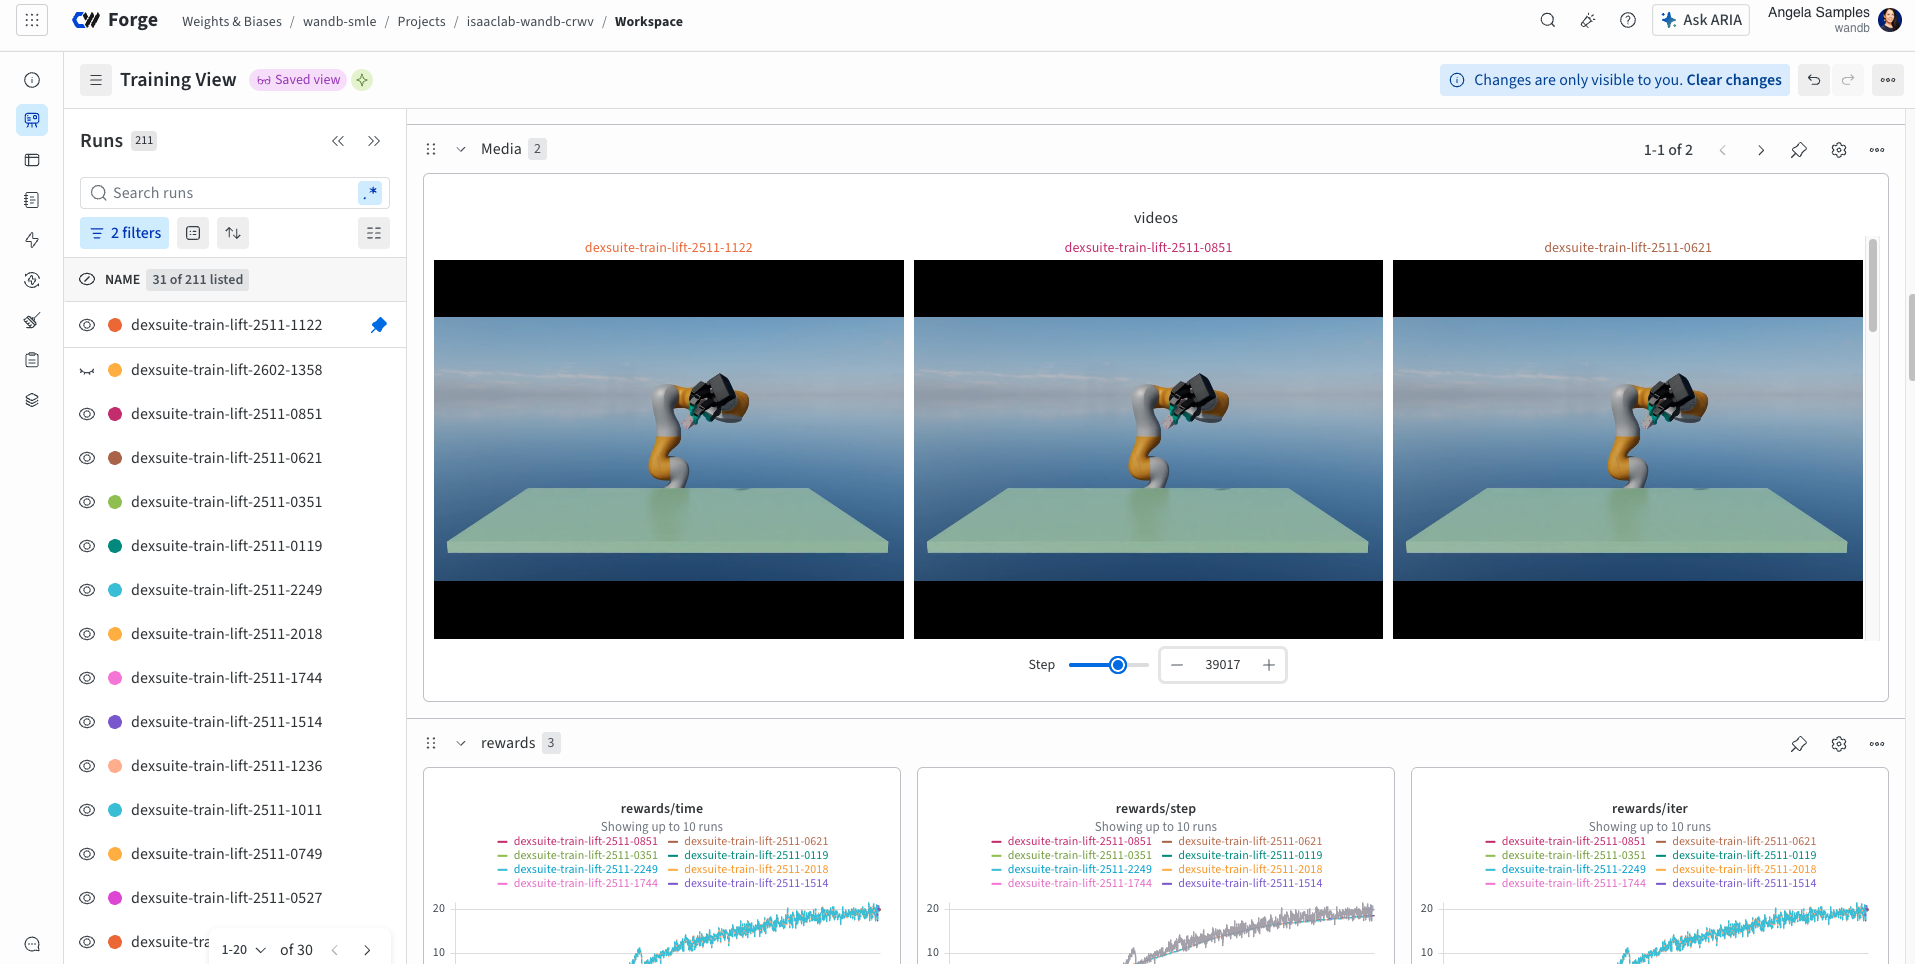
Track, version, compare, and reproduce multimodal experiments in a few lines of code, cutting tracking time from hours to minutes. Run hundreds of thousands of experiments, and let every run compound into the record that makes the next one smarter. Interactive visualization tools help you explore data, uncover insights, and catch improvements or regressions fast.

HYPERPARAMETER SEARCH

Hyperparameter search and optimization

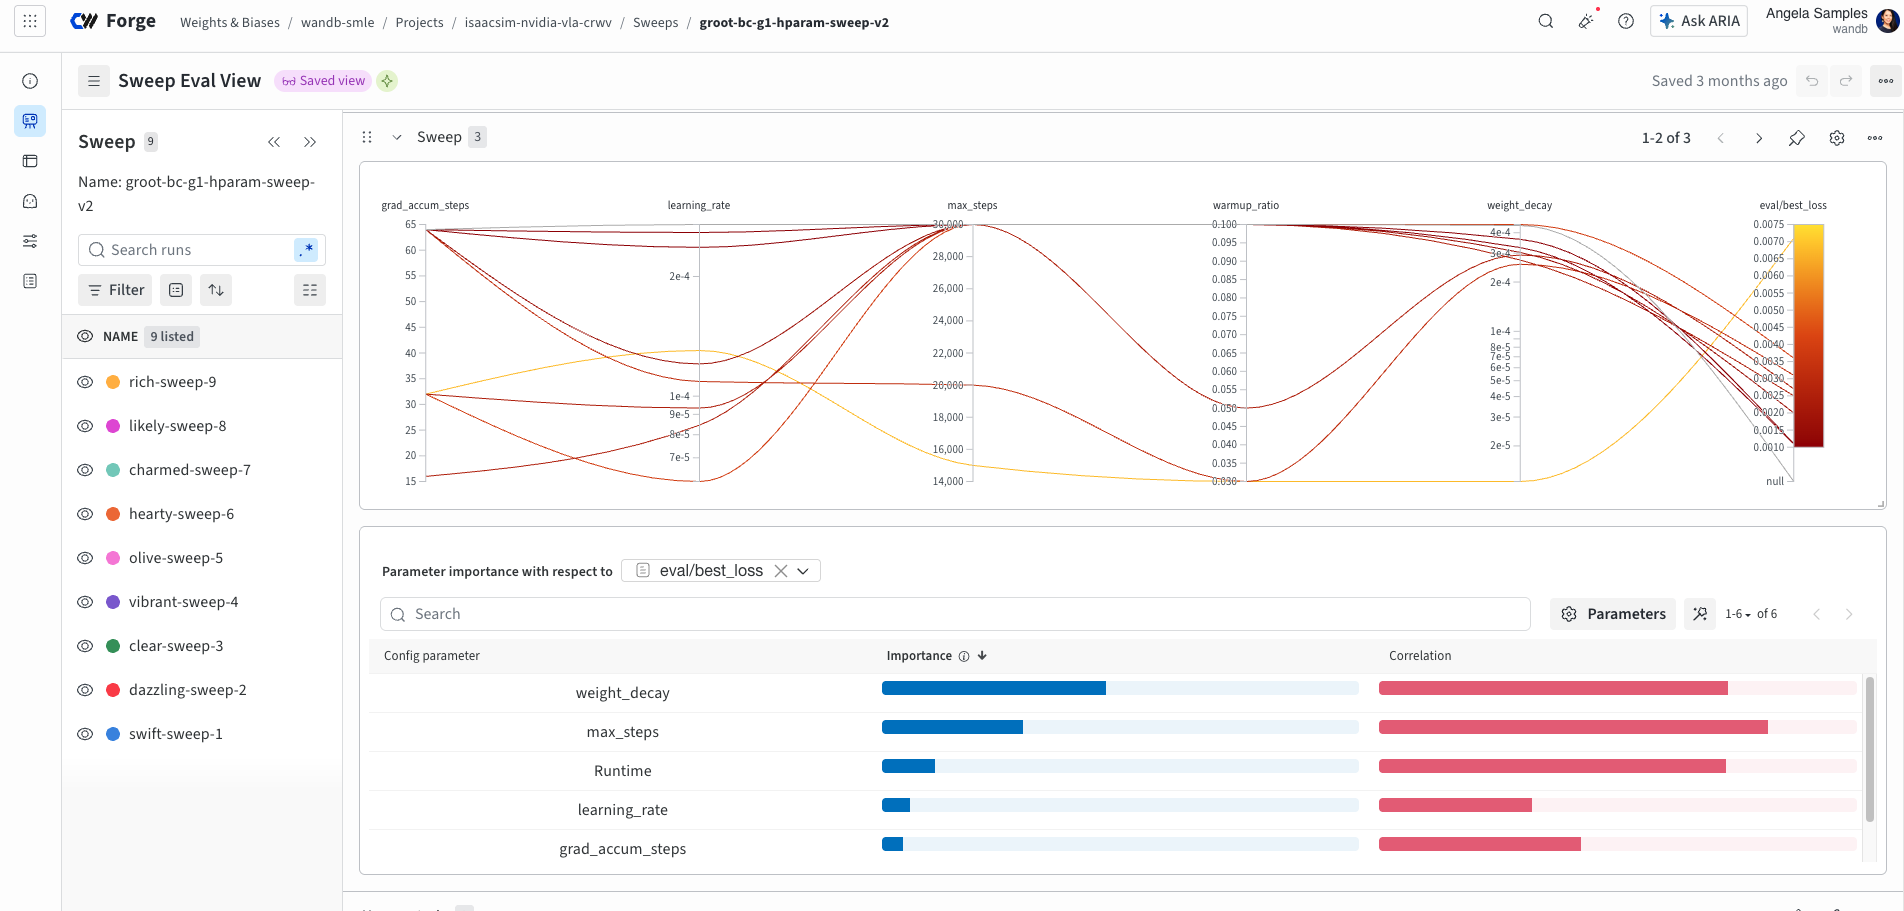
Automate hyperparameter search and optimization to find the best-performing configurations without manually managing every experiment. Choose from Bayesian optimization, grid search, or random search, customize parameter distributions and search logic, and use early stopping to focus compute on the most promising runs. Track progress, logs, and visualizations in one shared workspace so every result is transparent, reproducible, and easy to compare.

EVAL TABLES

Visualize and evaluate model performance

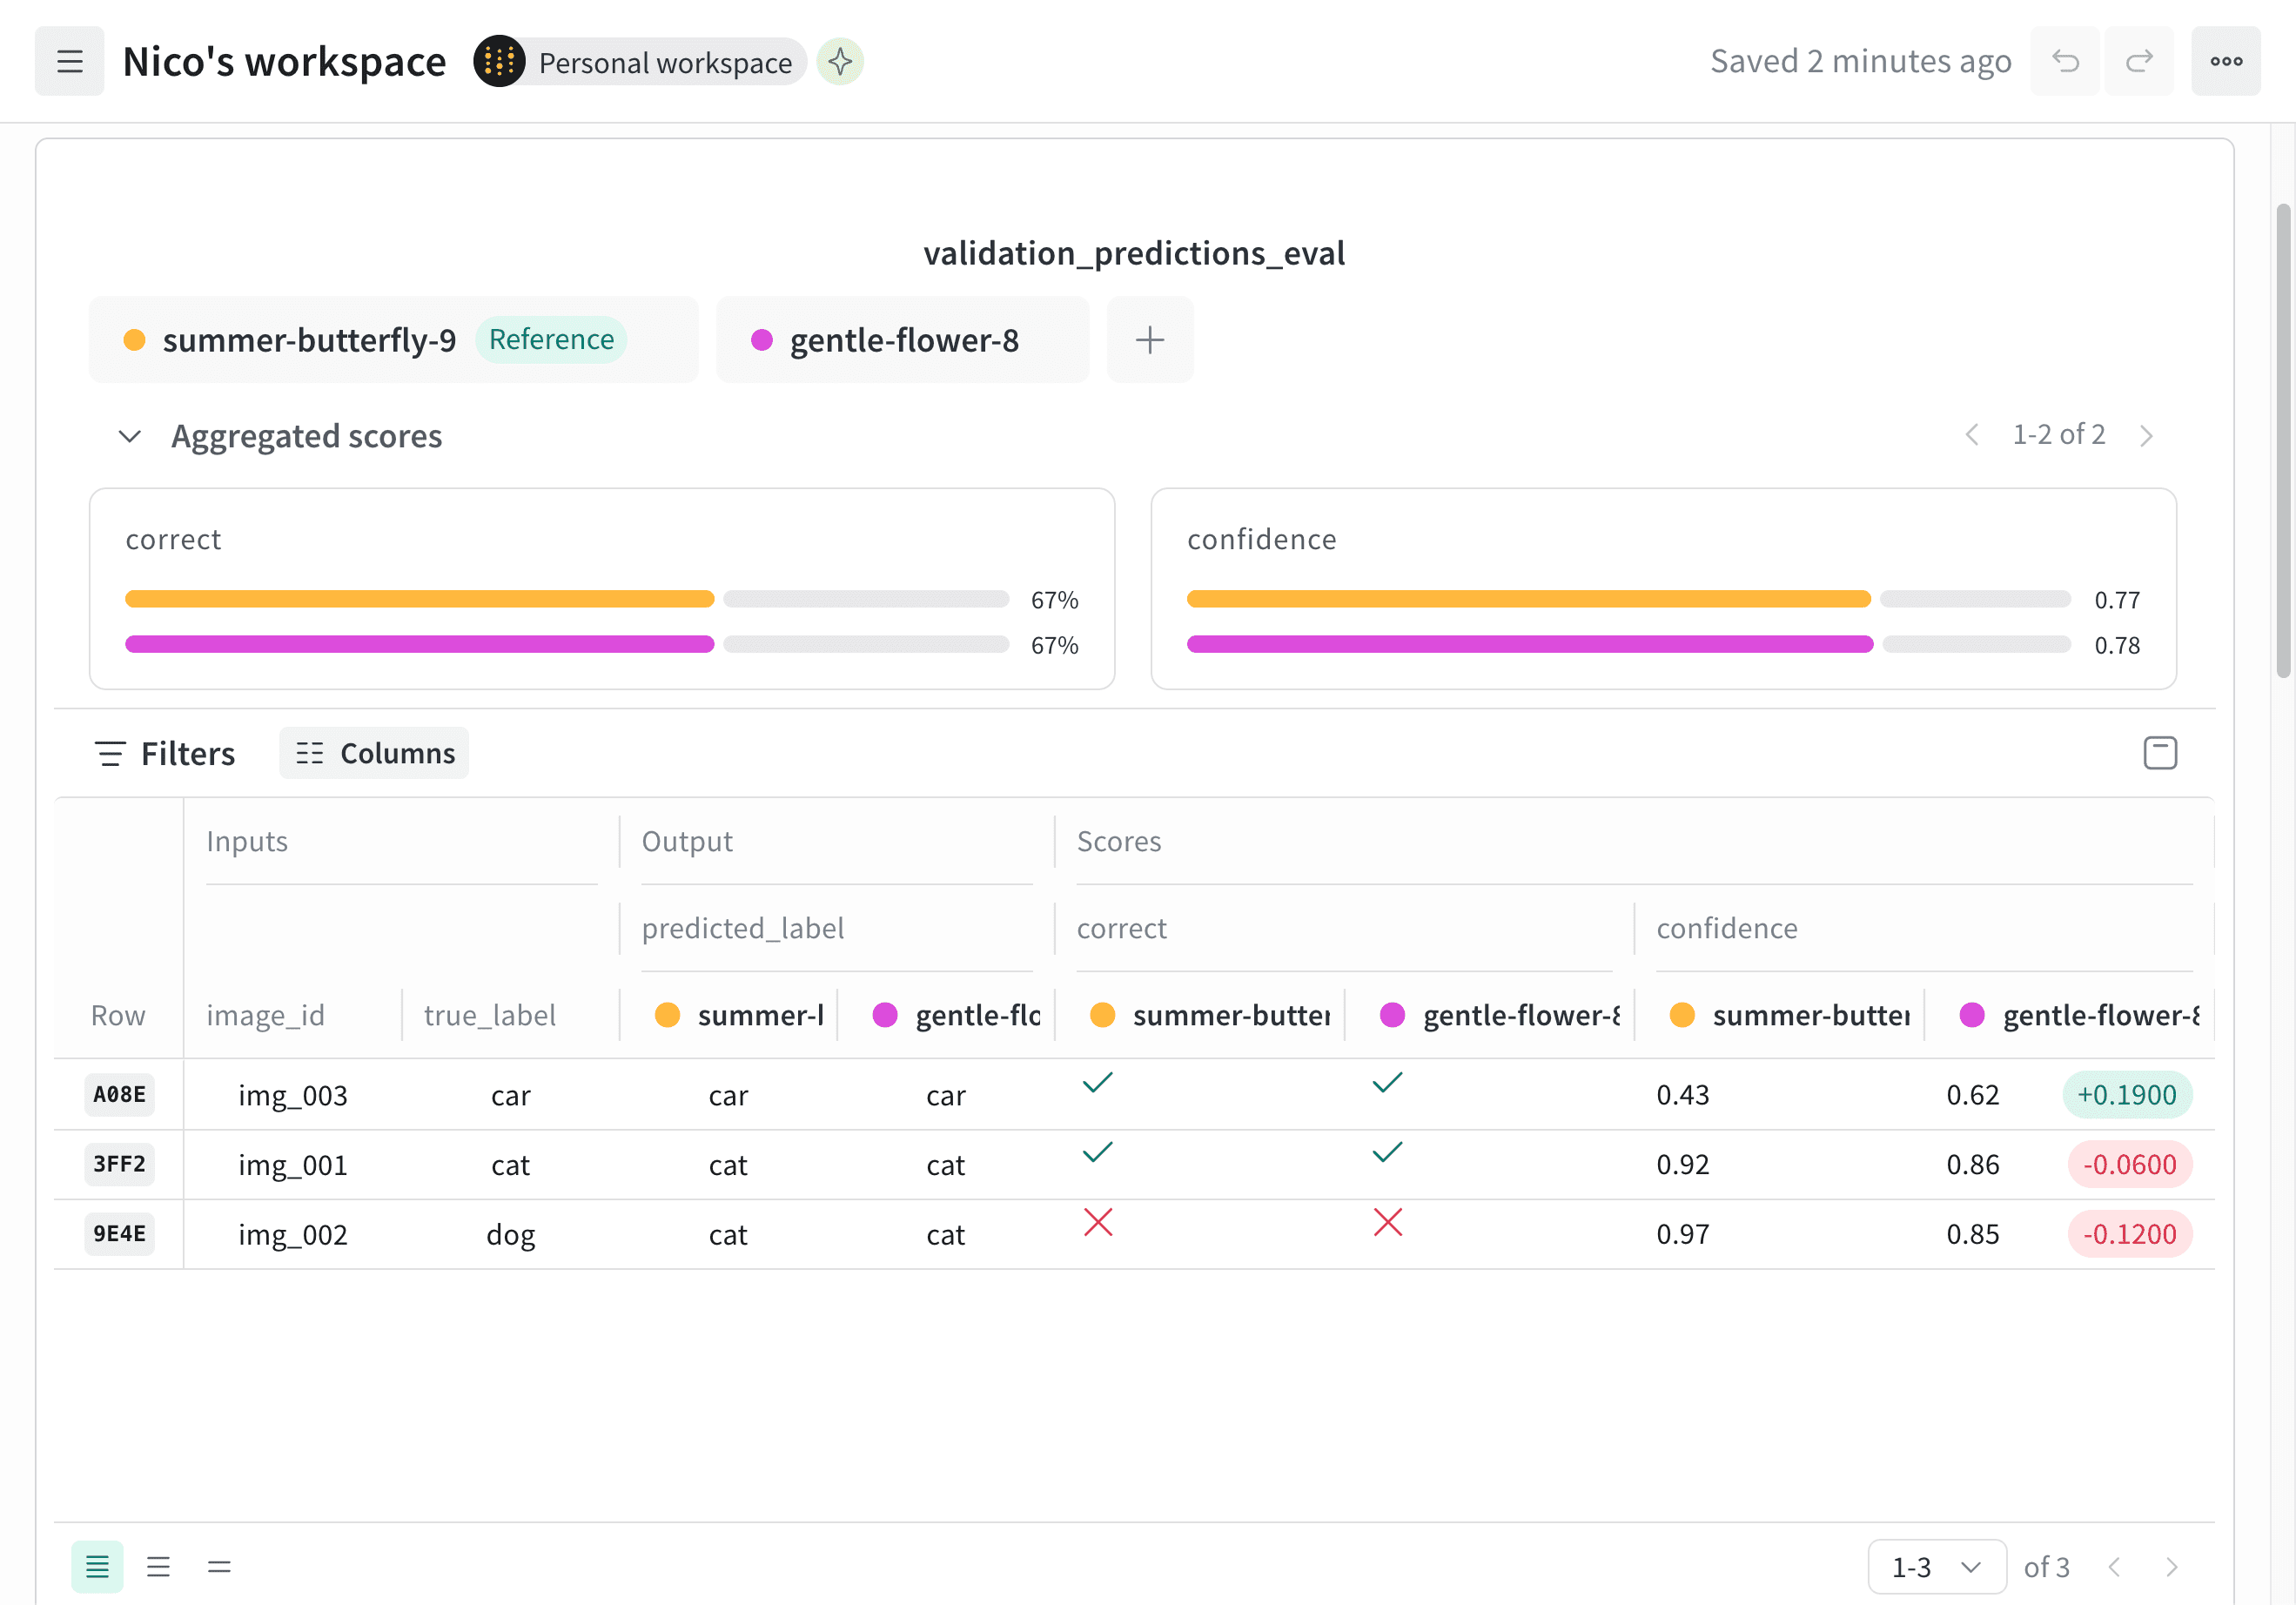
Eval Tables help you compare aggregate evaluation scores alongside example-level model inputs, outputs, and scores across multiple runs. Use them to evaluate model versions or training checkpoints, identify meaningful changes in performance, and investigate the specific examples behind those changes. Interactive visualizations make it easier to uncover patterns, diagnose weaknesses, and determine where to focus your next iteration.

reports

Share insights and enhance collaboration in deep learning projects

Reports help you document findings from AI experiments and turn results into clear, shareable narratives for teammates and stakeholders. Combine live visualizations, data, and commentary in one place to communicate progress, gather feedback, and plan next steps. Reports update automatically as new results arrive, making it easy to compare projects, establish benchmarks, and keep everyone aligned.

AUTOMATIONS

Automate workflows across the AI lifecycle

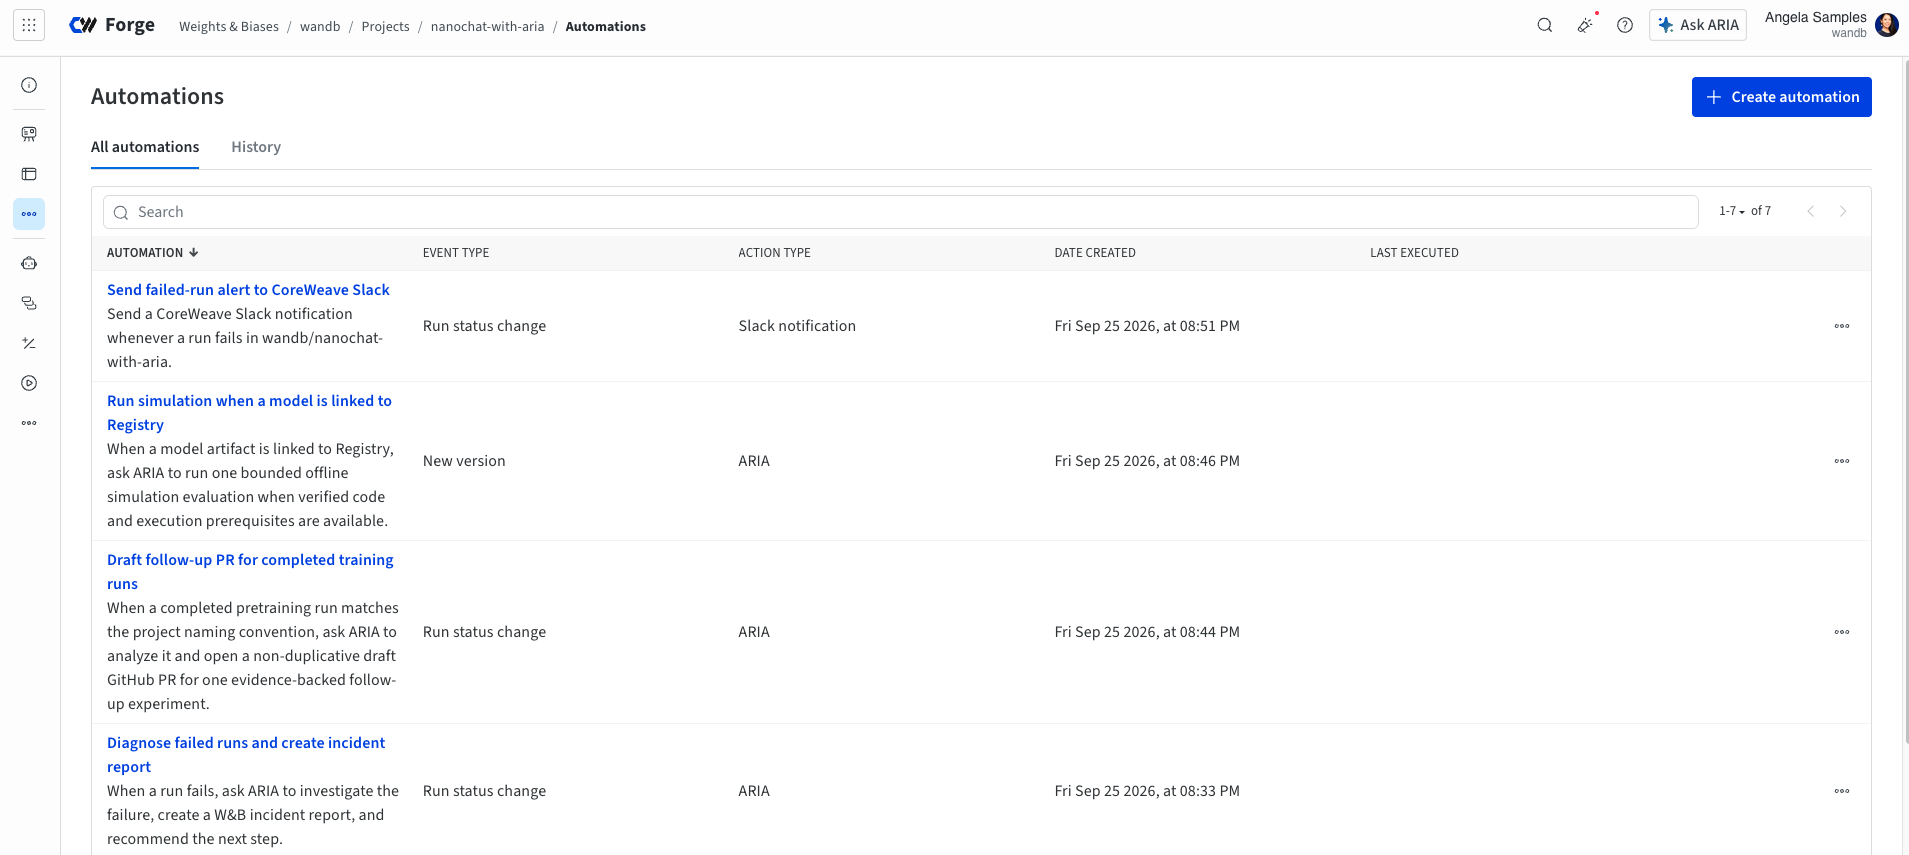
Automations help teams trigger workflows in response to events across projects, registries, and collections. Define an event and optional conditions, then automatically send a Slack notification, call a webhook, or prompt ARIA to take action. Notify teams when runs fail, initiate deployment when a production alias is assigned, or ask ARIA to compare a new model version against production. Automations reduce manual handoffs and keep development, evaluation, and deployment workflows moving.

INFRASTRUCTURE OBSERVABILITY

Optimize training with infrastructure observability

Track GPU, CPU, memory, network, and other system metrics alongside model performance to identify bottlenecks, improve hardware utilization, and control training costs. Prebuilt integrations with platforms such as NVIDIA eliminate the need to configure system metrics logging manually.

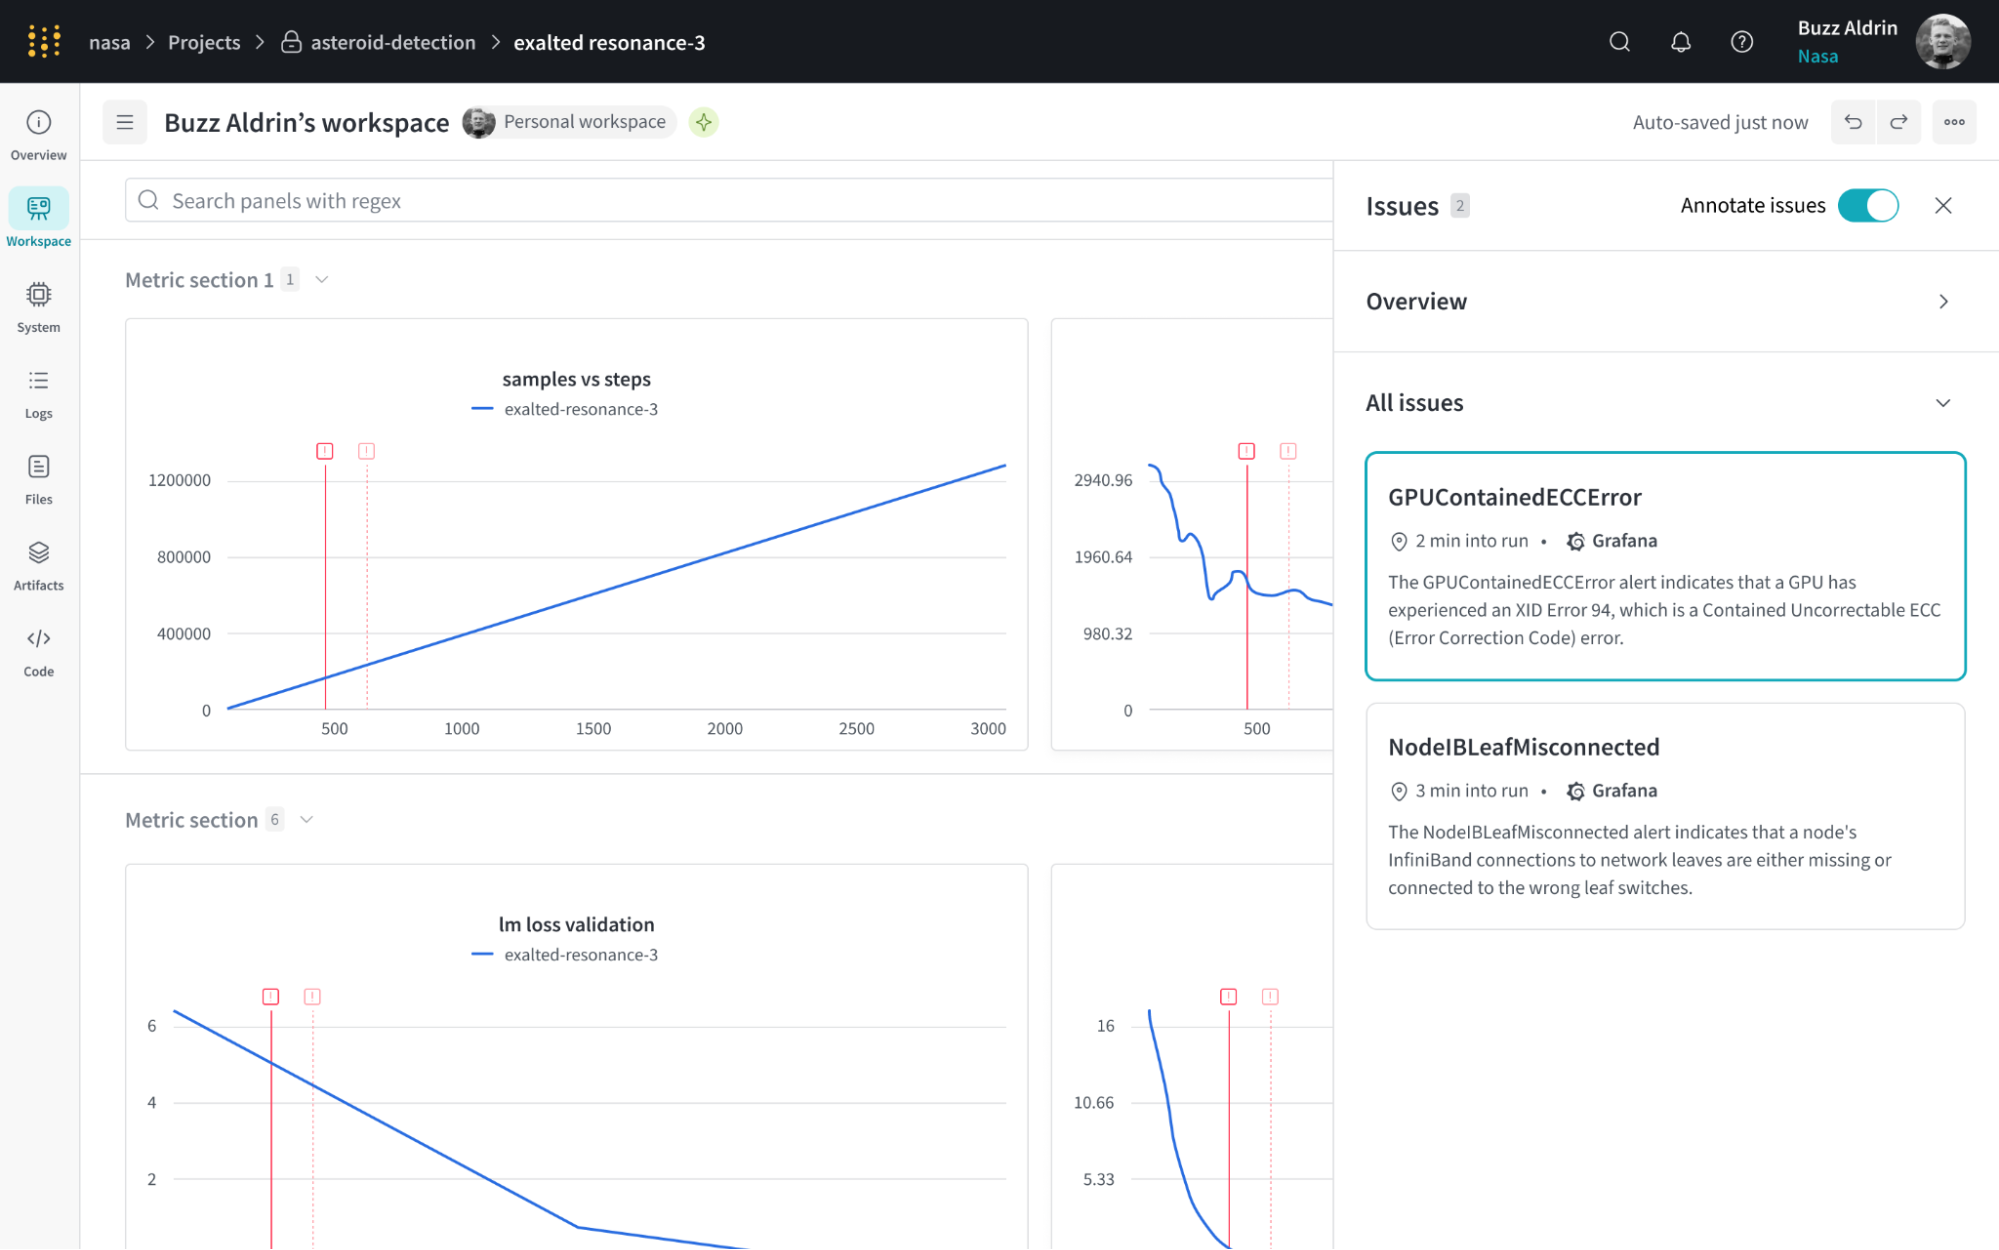
When training on CoreWeave’s industry-leading infrastructure, events from Mission Control appear directly within your W&B workspace, contextualized to the relevant training runs. Review timelines, GPU errors, network timeouts, service bottlenecks, and remediation guidance in one place to troubleshoot issues faster and optimize training and fine-tuning workloads.

DIRECT-TO-EXPERT

Talk to an engineer, not a ticket queue

When a run breaks or a metric doesn't add up, Direct-to-Expert support routes you straight to the engineers who build and operate the platform, at no additional charge. No tiers to escalate through, no waiting on a generalist to loop in someone who actually knows the stack.

Mobile app

Available on the go

The first iOS app to monitor AI experiments and track training runs anytime, anywhere.

ENTERPRISE READY

Built for enterprise scale and control

Deploy Agent Lens where your environment requires, keep sensitive data where it belongs, and connect production insights back to model development.

Deploy on your terms

Run Agent Lens as SaaS, in a dedicated cloud, or on-premises—so deployment fits your infrastructure and security requirements.
Keep control of your data

Bring your own bucket to keep regulated or security-sensitive data where it needs to live.

Close the loop back to training

Connect Agent Lens with Weights & Biases Models so production failures become signals for future training runs—not issues stranded in a bug tracker.

Scale with lower cost

With CoreWeave’s cost-efficient inference, Agent Lens optimized the performance teams need to continuously improve agents as usage grows.

Pioneers build their AI Loop on W&B Models

MasterClass is teaching its AI the way it teaches everything else, with rigor. Hundreds of thousands of traces captured across millions of lesson spans, all logged and tracked with W&B tooling, then put to work debugging hard questions and turning failures into training data. 
W&B MODELS IS PART OF COREWEAVE FORGE

Connected to the entire AI development lifecycle

A better model starts with evidence from production. W&B Models is where you improve: it tracks every run and promotes the winner, and what you train deploys straight back to Run. Connected to Agent Lens, CoreWeave RL, and Registry, it turns agent failures into training signals, reinforcement learning into better models, and successful versions into governed deployments.
Run

Observe

Curate

Observe

Evaluate

Related resources

The same news reads differently depending on where you sit. Here’s the version that applies to you.
DOCS

W&B Models documentation

use case

W&B Models for physical AI

use case

W&B Models for quant trading

Builder Resource Center: Learn from every run

Explore demos, code, and technical resources for every stage of the AI loop. Learn how researchers, developers, and CoreWeave engineers build, observe, evaluate, and improve AI systems—and put those insights to work.